News
September 24, 2026
My Unified Analysis paper was accepted to NeurIPS 2026! July 10, 2026
My SUN and Unified Analysis papers were accepted to EWRL 2026! June 1, 2025
I started my postdoctoral work at Aalto University! April 17, 2025
I have successfully defended my PhD thesis! February 6, 2025
I added my new paper on Value Iteration analysis with
absolute probability sequences to the website! January 22, 2025
My MDP Geometry paper was accepted to AISTATS 2025! January 8 & 9, 2025
I presented my MDP Geometry paper in the Technion (Shie Mannor's lab) and
TAU (Tomer Koren's lab). October 2, 2024
I presented my MDP Geometry paper at the seminar in University of Cyprus
(announcement)
September 16, 2024
Since my US visa is still not ready, I came to Cyprus where I will stay as a visiting
researcher at University of Cyprus. July 17, 2024
My TD-SVRG paper was accepted to TMLR 2024!
|
|
|
Arsenii Mustafin
My current postdoctoral position ends in May 2027, so I am looking for my next postdoctoral opportunity.
If you are aware of an opening in a lab interested in advantage-based algorithms and exploration,
temporal structure, or goal-conditioned reinforcement learning (GCRL), please let me know.
I am a postdoctoral researcher at Aalto University (Finland) working with
Prof. Dominik Baumann and
Prof. Joni Pajarinen.
My research interests are theoretical and practical aspects of reinforcement learning.
I recieved my PhD from
Boston University, department of Computer Science,
whre I was advised by Prof.
Alex Olshevsky and
Prof.
Yannis Paschalidis.
During my PhD I worked on SemaFor DARPA project with BU team lead by Prof.
Kate Saenko
and a project on Explainable AI with
Prof. Sarah Adel Bargal.
Research topics: My primary research interest is reinforcement learning theory and
theoretically grounded algorithms. My main contribution in this area is a geometric interpretation of Markov decision processes,
and I am currently focusing on advantage-based algorithms. My second research direction examines the interaction between exploration,
goal-conditioned reinforcement learning, and the temporal structure of MDPs. If you work on either of these topics, I would be happy to chat.
Previously I was studying economics, and took several undergraduate
and graduate-level courses on econometrics and time-series analysis.
Prior to coming to BU, I worked as a machine learning developer.
I spent four years in Mainland China and speak fluent Mandarin, in addition to fluent English and native Russian.
aam [at] bu.edu |
CV |
LinkedIn |
Github |
IG (personal)
|

|
|
|
Revisiting Value Iteration: Unified Analysis of Discounted and Average-Reward Cases
Mustafin A., Sheng X., Baumann D.
Accepted to NeurIPS 2026
In this work, we develop a unified geometry-based analysis of Value Iteration in discounted- and average-reward settings. We show
that geometrically Value Iteration has exactly the same dyncamis in two cases.
This allows us to show that under a unique and unichain optimal policy, VI converges geometrically in both settings with a rate faster
than previous analysis suggests.
|
|
|
SUN: Reaching for Novelty in Reinforcement Learning
Yang W., Mustafin A., Baumann D., Pajarinen J., Parisi S.
EWRL, 2026
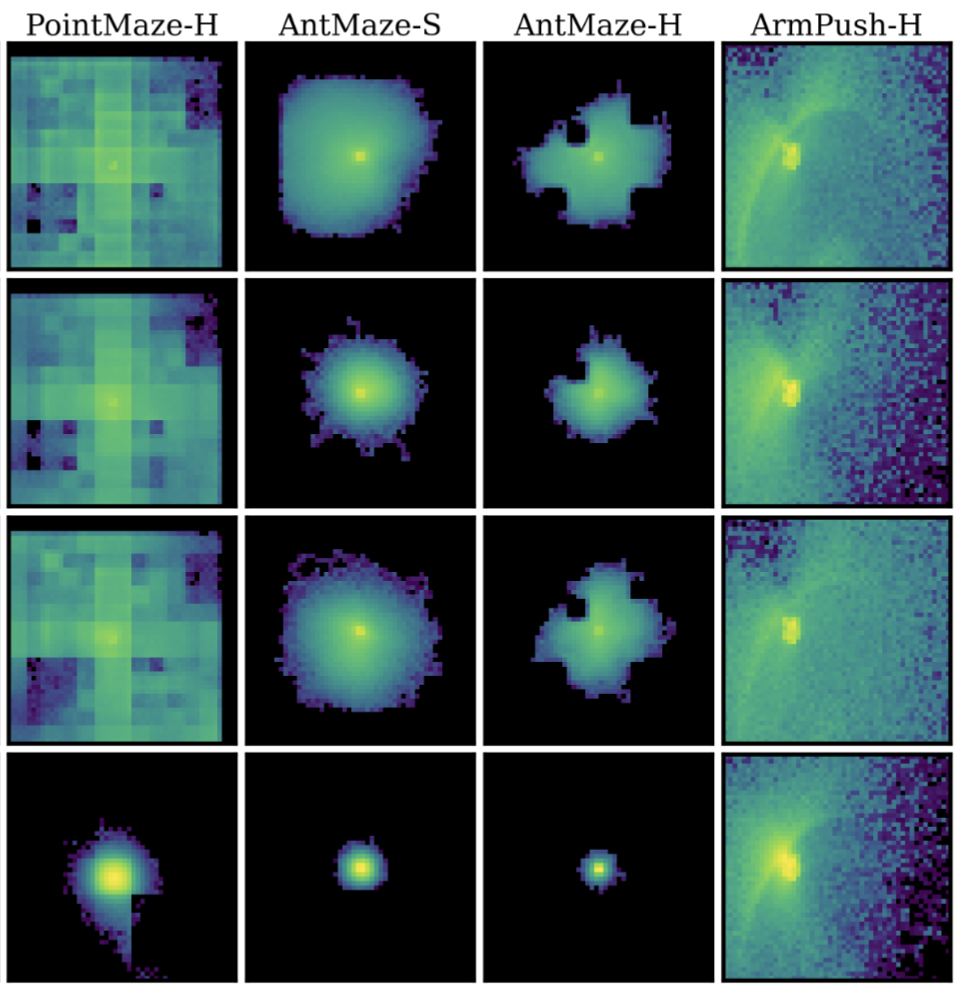
In this work, we introduce SUccessor-to-Novelty (SUN), a Goal-Conditioned RL-based exploration
algorithm, which uses reachability-aware goal-selection framework that identifies goals
that are both novel and reachable. SUN can be integrated into off-policy reinforcement learning algorithms and consistently
outperforms state-of-the-art exploration methods in terms of entropy and coverage across a range of challenging environments.
|
|
|
MDP Geometry, Normalization and Reward Balancing Solvers
Mustafin A., Pakharev A., Olshevsky, A., Paschalidis, I.
Accepted to AISTATS 2025
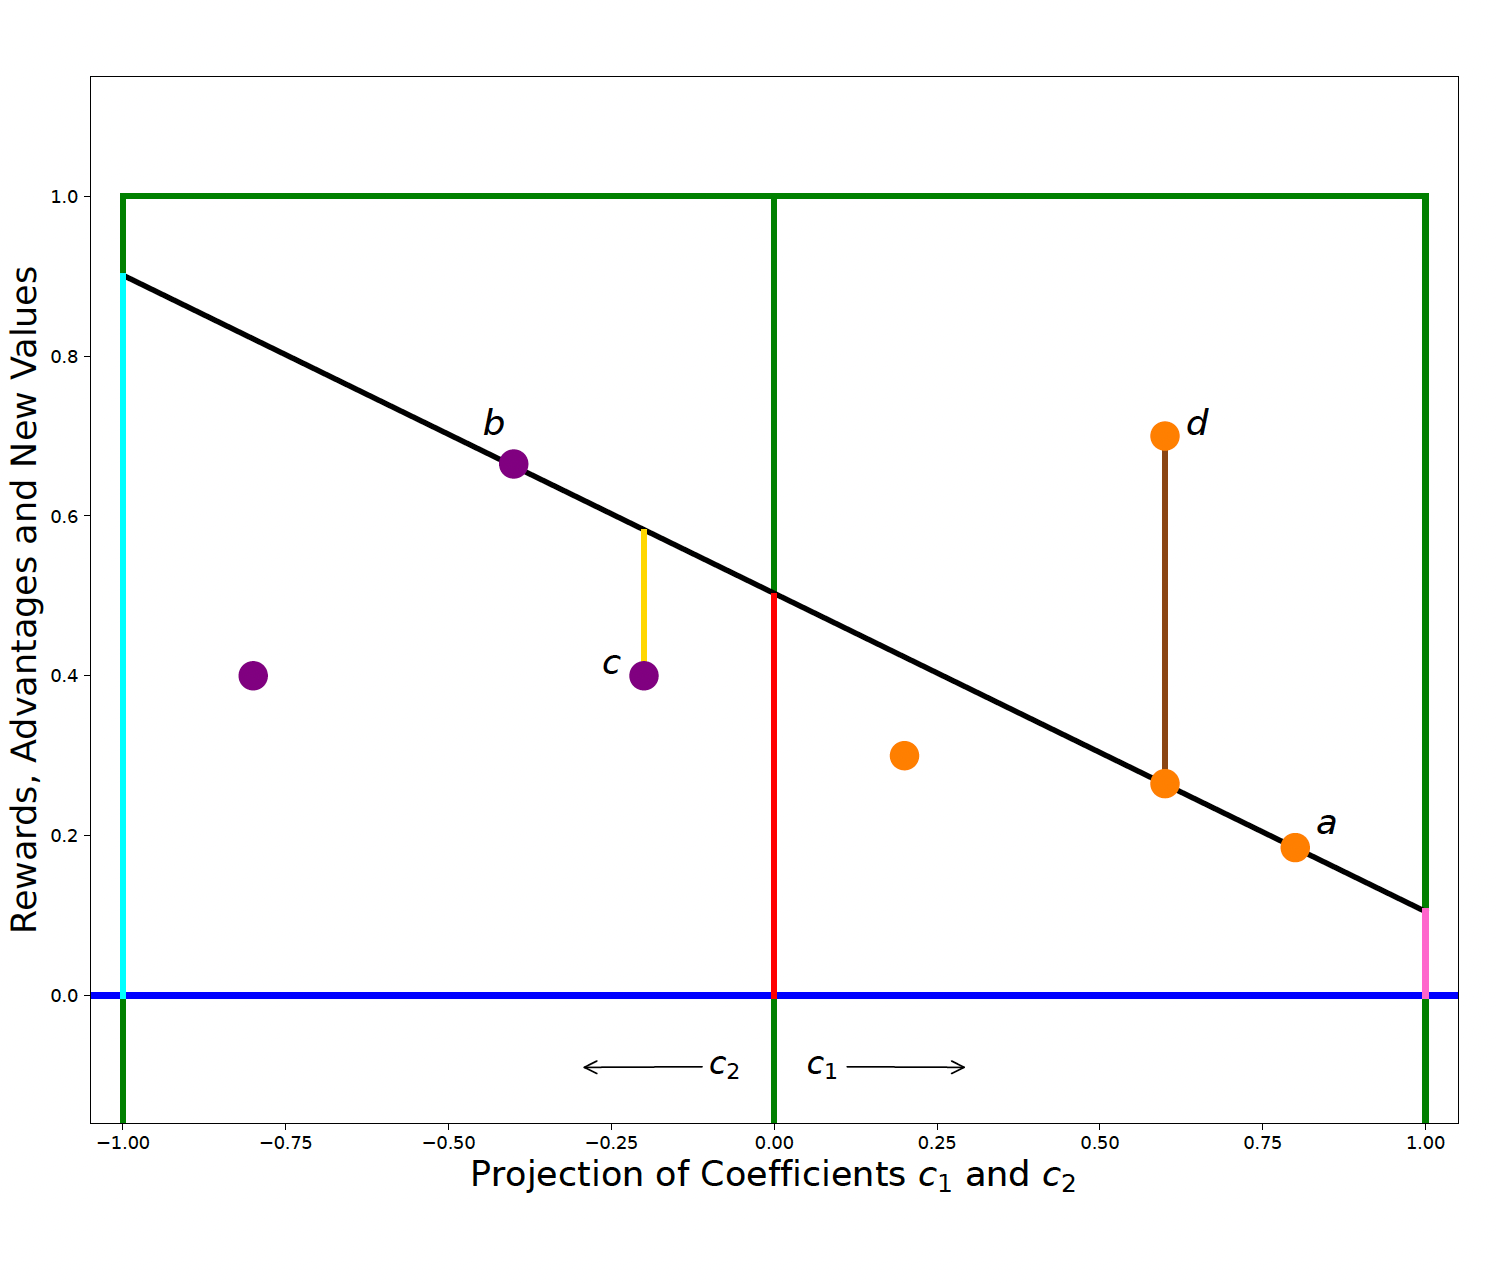
In this work we suggest a new geometric view on MDP, which allows to interpret the main MDP problems as geometric problems.
Inspired by this view we propose a Normalization procedure which transforms an MDP to a form, in which finding optimal policy
is trivial. It enables a new class of MDP solving algorithms, which we call Reward Balancing Solvers. One algorithm from
this class, Safe Reward Balancing (RB-S) achieves and exceeds the state-of-the-art convergence guarantees in known MDP
(Value Iteration), unknown MDP (Q-learning) and federated unknown MDP (Federated Q-learning) settings.
|
|
|
Analysis of Value Iteration Through Absolute Probability Sequences
Mustafin A., Colla, S., Olshevsky, A., Paschalidis, I.
Currently under review, 2025
In this work, we use absolute probability sequences to develop a new line of analysis of Value Iteration algorithm
and examine its convergence in terms of the L² norm, offering a new perspective on its behavior and performance.
|
|
|
Closing the Gap Between SVRG and TD-SVRG with Gradient Splitting
Mustafin A., Olshevsky, A., Paschalidis, I.
TMLR, 2024
In the paper, my coauthors and I significantly improve theoretical guarantees of SVRG method applied to TD update,
show that it exhibits the same convergence
as SVRG in convex optimization setting and provide theoretical guarantees for practical algorithm.
|
|
|
Ani-GIFs: A Benchmark Dataset for Domain Generalization of Action Recognition from GIFs
Mustafin, A.*, Jain, S.*, Lteif, D.*, Majumdar S.*,
Tourni, I.*, Bargal S., Saenko K., Sclaroff S.
Frontiers in Computer Science, 2022
This paper published in "Frontiers in computer science" presents a dataset for
Domain Generalization problems in the video domain.
|
|
|
Patent: SYSTEMS AND METHODS FOR IMAGE OR VIDEO PERFORMANCE HEAT MAP
GENERATION
Mustafin A., Saraee E., Hamedi J., Halloran Z.
US Patent, 2021
The patent application was a result of my internship at Vizit labs, Inc, during which I
played a key role in developing an explainability technique for computer vision model.
|
|
|